 Cloud
Luna · DSH Standard Mode
11:45
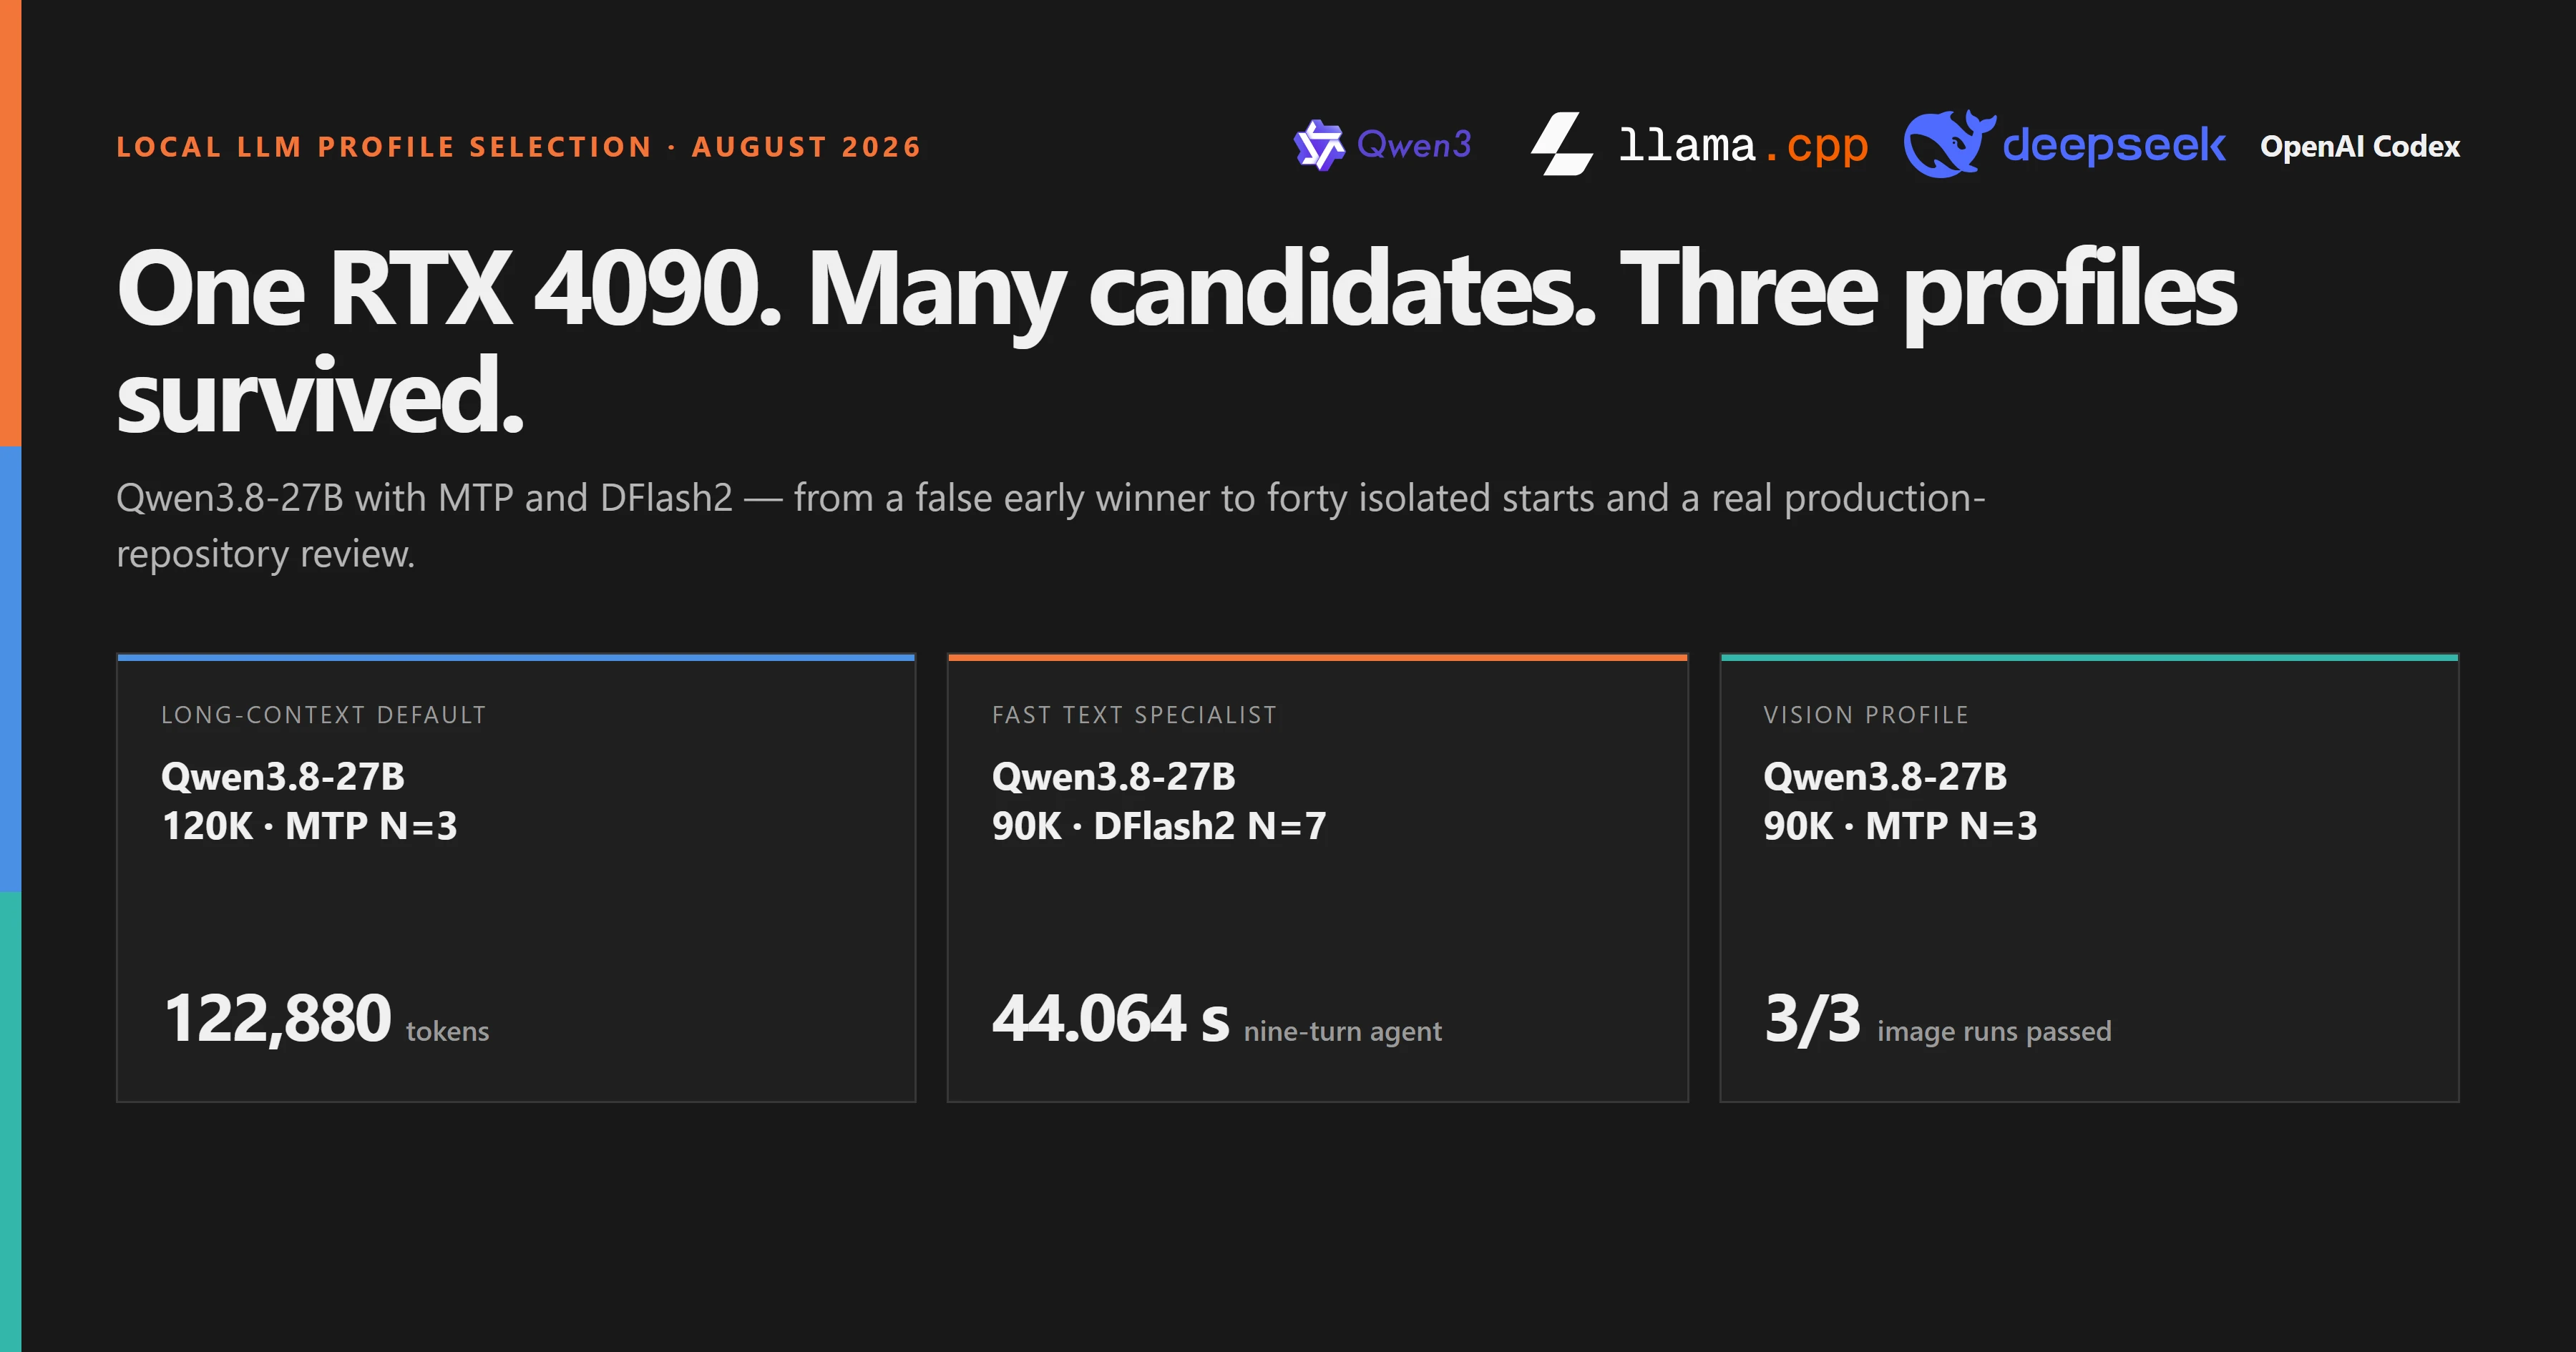
On one RTX 4090, MTP and DFlash2 profiles were eliminated stage by stage. The result is not one universal winner, but a 120K MTP default, a fast 90K DFlash2 text specialist, and a verified 90K MTP vision profile.
Coding agent runtime benchmark
Four conditions. One task, one repo, one rubric.
Same task · 99–100/100 rubric score · net 11:45–54:48
Cloud11:45
Cloud13:48
 llama.cppLocal
19:57
llama.cppLocal54:48
Four conditions solved the identical task in the identical repository and every one scored 99 or 100 out of 100. Net task time — with approval waits and automatic context compaction excluded from every measurement — ranged from 11:45 for the cloud run through DSH standard mode to 54:48 for the local model with speculative decoding off.
Coding agent runtime benchmark
Four execution stacks. One repository.
4 patches · all targeted tests passed · 6:04–13:57
Cloud6:04
Local8:04
 Cloud
12:54
Local13:57
Four coding-agent runs changed the same repository and passed their targeted tests. Wall time still ranged from 6:04 to 13:57 because model, harness, cache and review acted together.
AI agent interface benchmark
One model. Four interfaces.
5 tasks · 20 fresh runs · 12/12 quality checks
The same AI model, four agent interfaces and five real repository tasks: what actually changed in quality, token volume, runtime and working style.
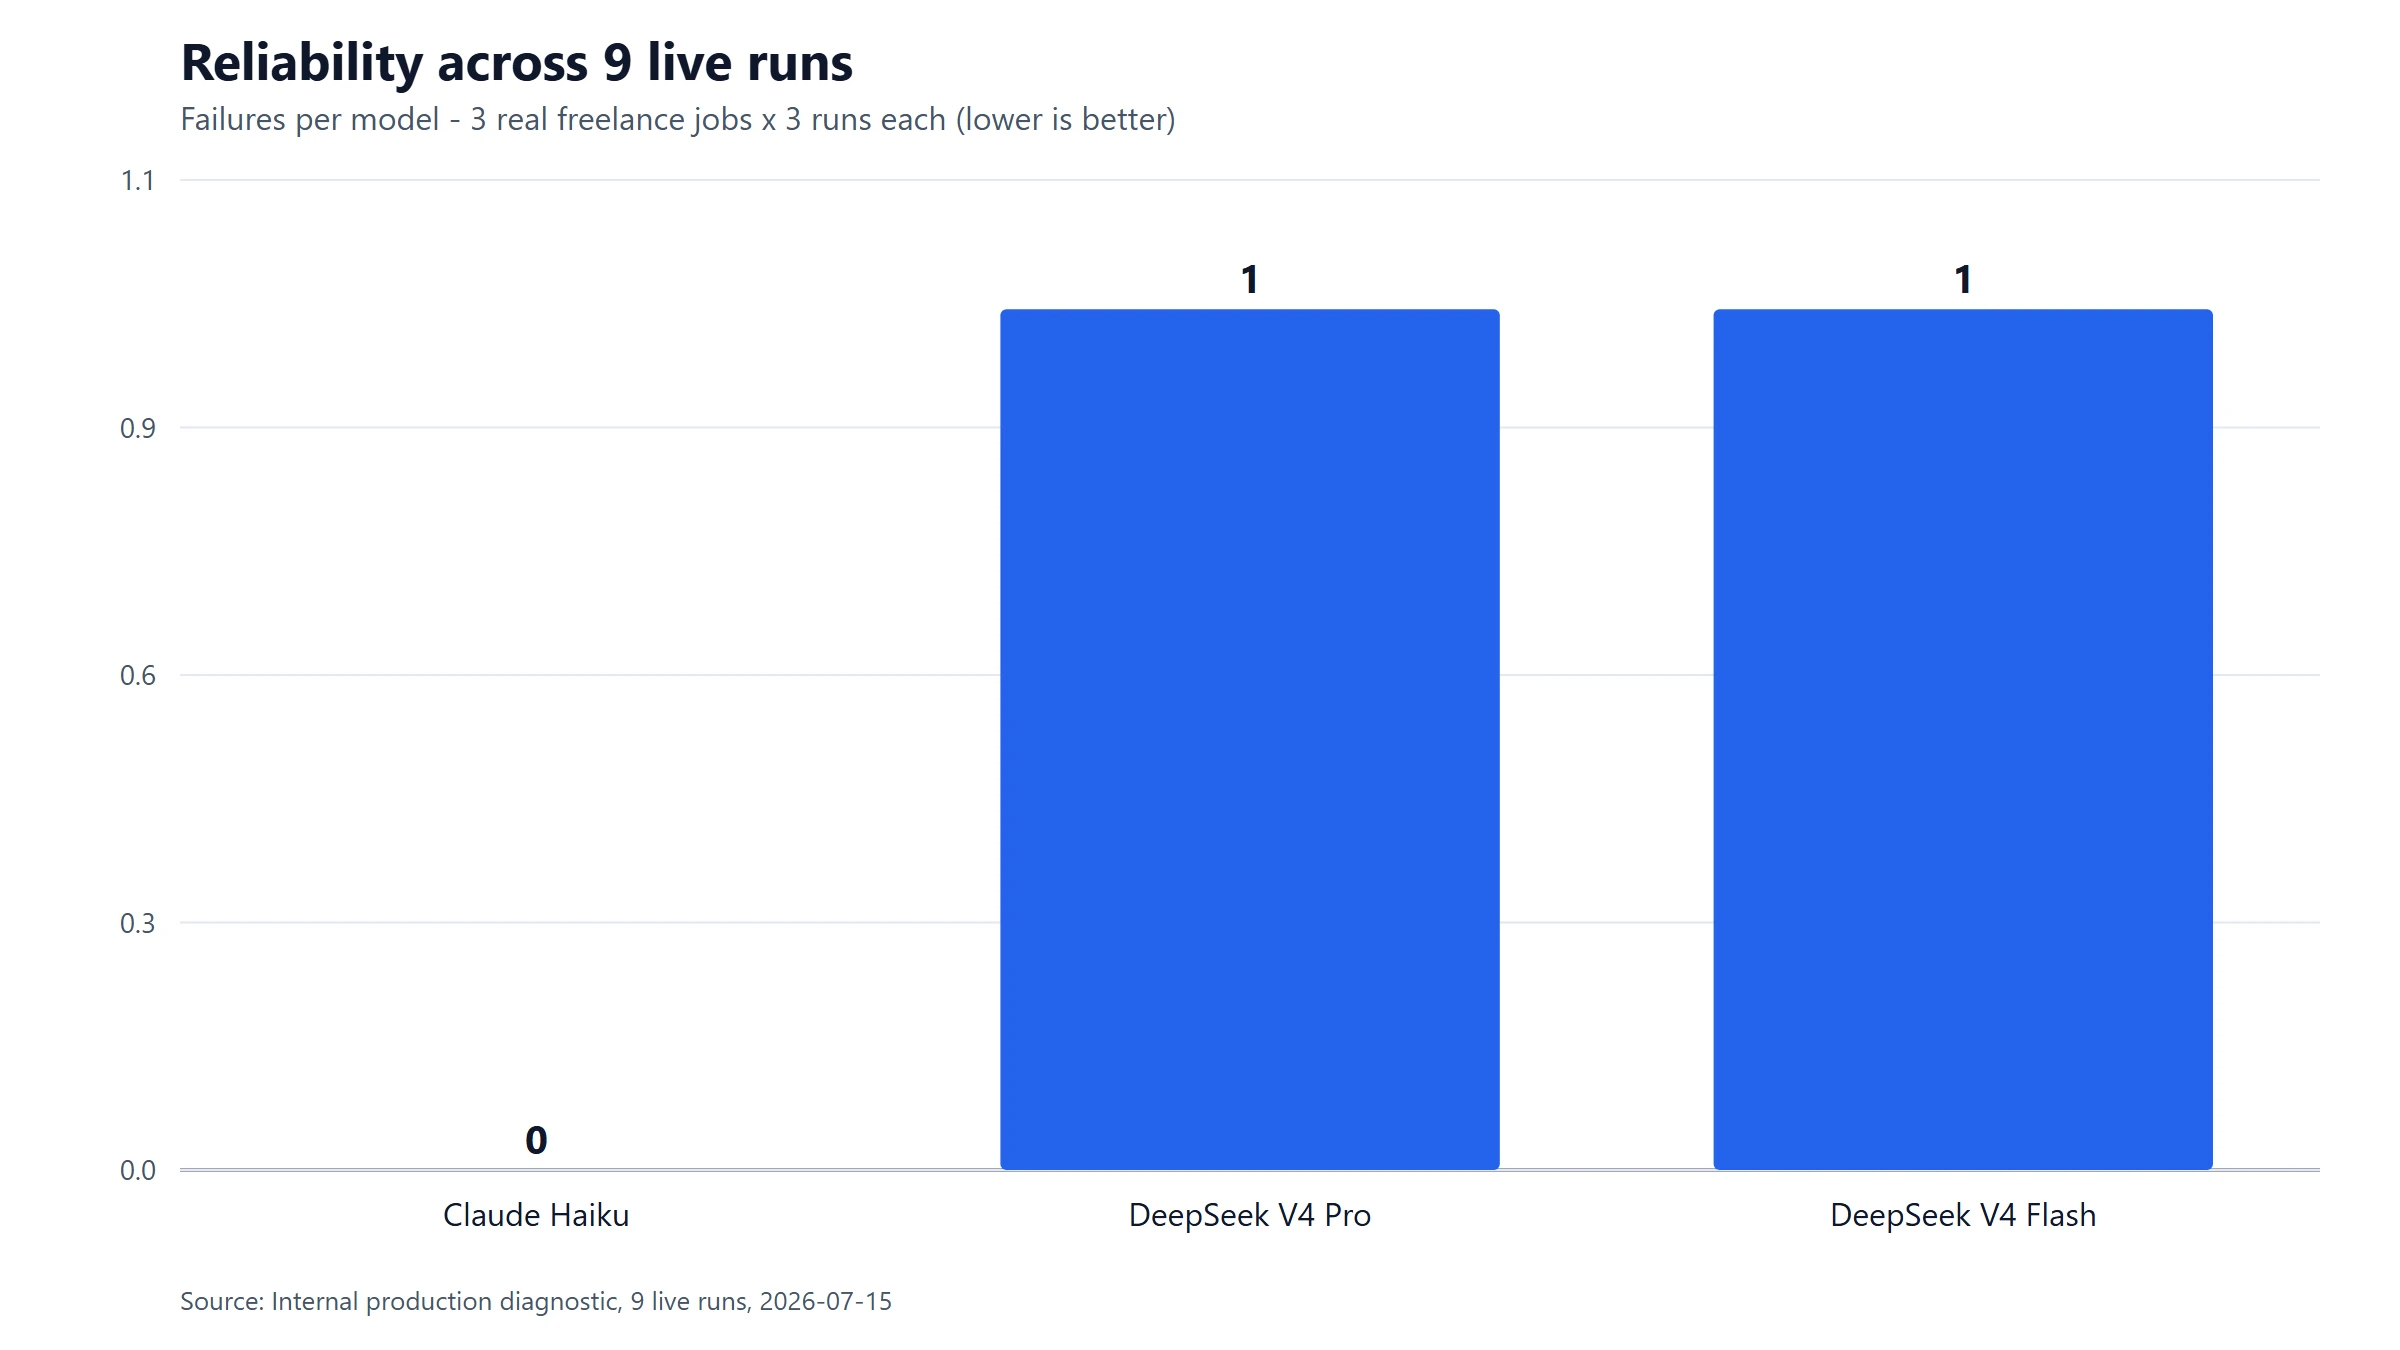
I tested Claude Haiku against DeepSeek V4 Pro and Flash on my own AI proposal-writing pipeline, using three real freelance jobs. Here's what held up.